Beats the general model — or it doesn't ship.
Earning The Right To Replace A General ModelA benchmarking framework built around regional-language tasks, used to check whether a specialized Indic model actually outperforms a general-purpose model on the languages and tasks that matter — not a generic leaderboard score.
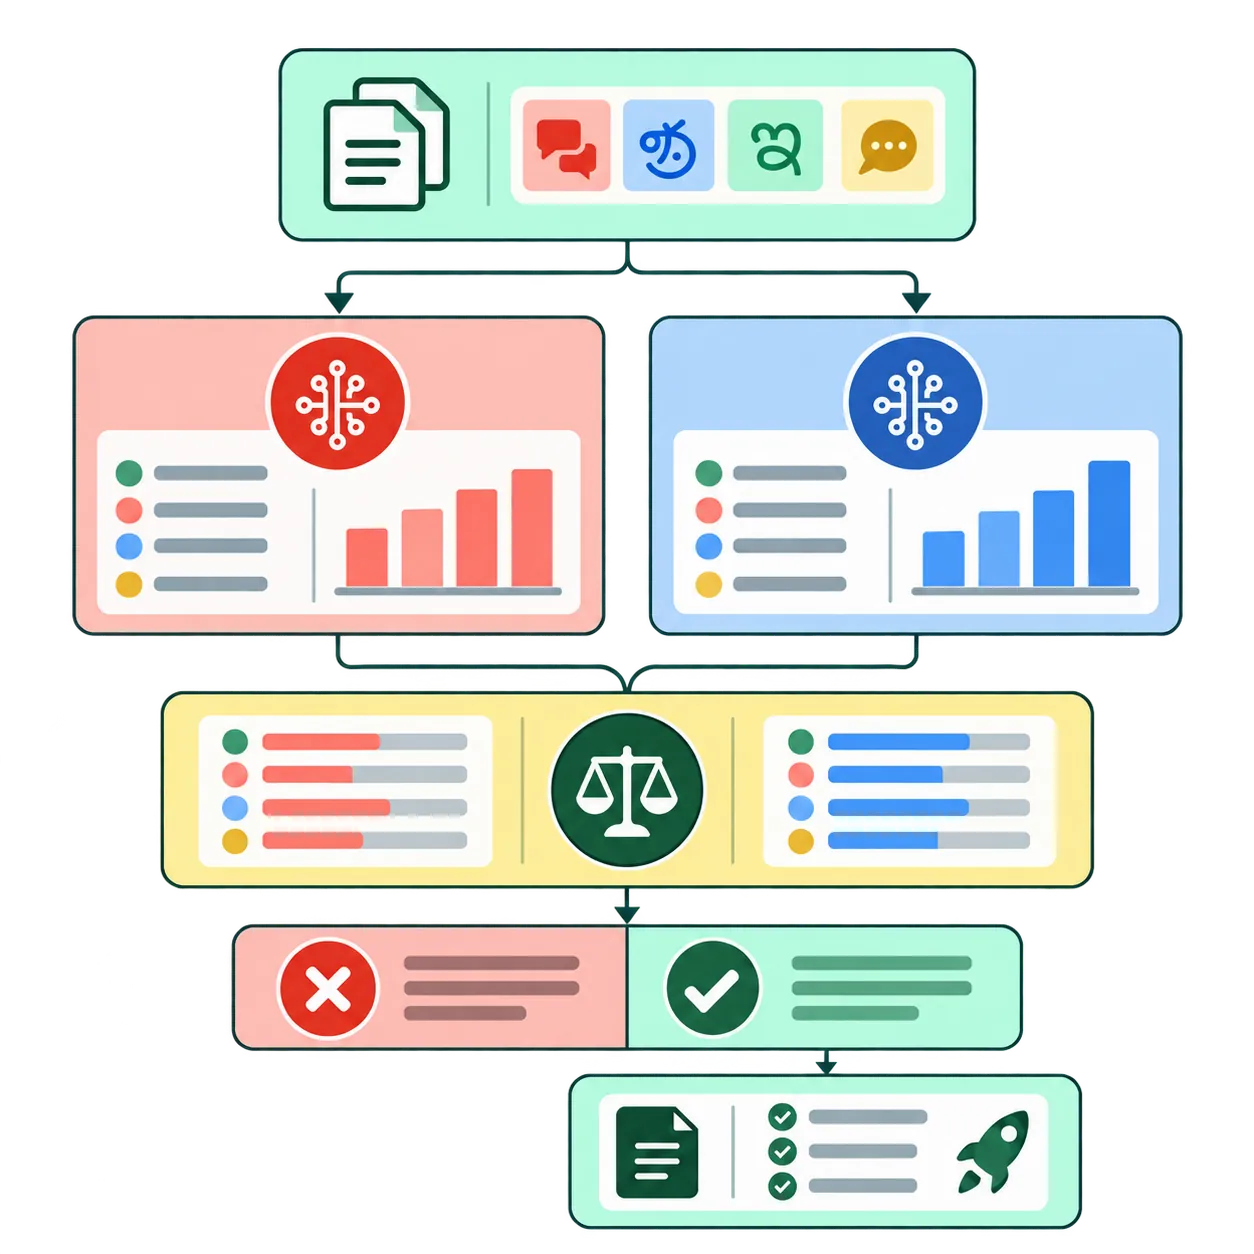
What Indic Eval delivers today
Built to prove specialization, not just measure it
Evaluation as a Gate, Not a Report
Specialized vs. General Benchmarking
Every specialized model is scored directly against a general-purpose alternative on the same regional-language tasks, so the comparison is a number, not an opinion.
Regional Language Task Coverage
Benchmarks are built around real regional-language understanding and generation tasks, rather than assuming English-centric benchmarks translate cleanly.
Run-Over-Run Regression Gating
Every model iteration is scored against its predecessor before it reaches production, so quality only moves forward.
Where Indic Eval drives value
Choosing Specialized Over General
Before committing to a specialized model for a regional-language workload, teams get a direct, task-level comparison against the general-purpose model it would replace.
- ✓Scoring runs on the same task set for both models, so the comparison is apples-to-apples.
- ✓Retrieval and generation are scored together, matching how the model is actually used.
- ✓Results are tied to the specific regional languages the deployment cares about, not an aggregate global score.
Continuous Quality Gating
Every new model iteration is evaluated before it is allowed to replace the one already in production.
- ✓A model iteration that scores worse than its predecessor does not ship, regardless of training metrics.
- ✓Evaluation runs alongside every training cycle, not as an occasional audit.
- ✓Findings feed directly back into what the next iteration needs to improve.