indiclabs.ai
Available[INDIC_HARNESS]

One runner for every benchmark, every model.

One Runtime, Any Benchmark

A harness is the infrastructure that actually runs an evaluation — not the test itself, but the plumbing that executes it the same way every time. Without one, every new benchmark needs its own setup, and results from different runs can't be trusted to mean the same thing. Indic Harness is that shared runtime: plug in any regional-language benchmark and it runs identically against every model, checkpoint, and iteration.
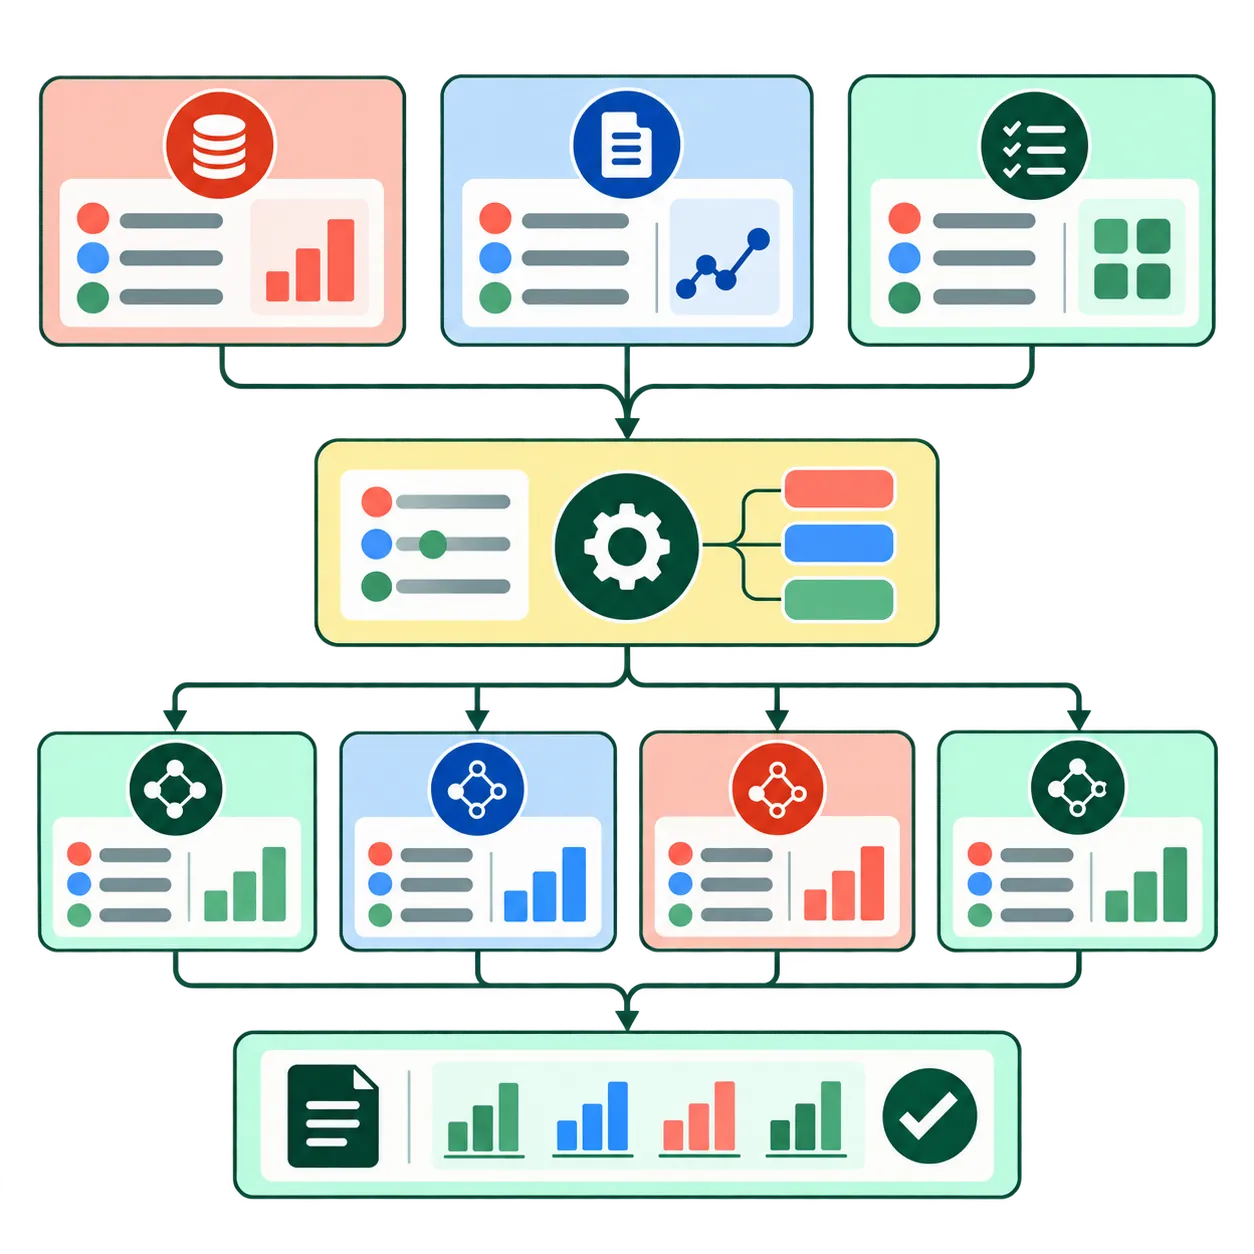
Benchmark suites entering one runner and producing comparable results across model runs
INDIC STACK FUNCTIONALITY

Why a harness matters

✓
A benchmark defines what to test — a harness is what actually runs it, the same way, every time
✓
Without a shared runner, every new test means new plumbing, and results that can't be compared to each other
✓
A harness is what turns "the model got better" from an impression into a number
✓
It's the difference between a test you can run once and one you can trust every time after
SYSTEM DESIGN

What Indic Harness delivers today

✓
A single execution runtime for running any benchmark or task suite against a model
✓
Consistent, repeatable runs — same setup, same scoring, every time
✓
Follows established open-source evaluation-harness patterns rather than inventing a bespoke runner
✓
The underlying execution engine can evolve without changing how the rest of the pipeline calls it
ENGINE CAPABILITIES

A Runtime Built to Stay Out of the Way

Pluggable Benchmark Execution

Any benchmark or task suite plugs into the same runner, so adding a new test doesn't mean building new infrastructure.

Consistent, Repeatable Runs

Every run follows the same setup and scoring path, so results are comparable across models, checkpoints, and time.

Engine-Agnostic by Design

The execution engine underneath can be swapped or upgraded without changing how the rest of the evaluation pipeline calls it.

REAL-WORLD DEPLOYMENTS

Where Indic Harness drives value

USE_CASE_01

Standing Up a New Benchmark Fast

When a new regional-language task set needs testing, it plugs into the existing runner instead of requiring its own execution pipeline.

  • ✓New task suites reuse the same runner, scoring path, and output format.
  • ✓No separate infrastructure stood up per benchmark.
  • ✓Consistent with how every other benchmark in the system runs.
USE_CASE_02

Comparing Across Model Iterations

Every model checkpoint runs through the same harness, so comparisons across iterations are apples-to-apples.

  • ✓The same runner executes every checkpoint, old and new.
  • ✓Results are directly comparable since nothing about the execution path changes between runs.
  • ✓Feeds directly into the gating decisions Indic Eval makes on each iteration.
RELIABILITY & GOVERNANCE

How Every Run Stays Comparable

✓
Same Runner, Every TimeEvery benchmark, model, and checkpoint executes through the same runtime, so no run is scored under different conditions than another.
✓
Swappable Execution EngineThe engine underneath the runner can change without changing how benchmarks are defined or how results are read.
SYSTEM SPECIFICATIONS

Architectural Parameters

Engine CorePluggable benchmark execution runtime built on established open-source evaluation patterns
Performance MetricStructured, consistent output format across every benchmark and model
Deployment ModelRuns alongside every Indic Eval scoring pass and training iteration
Linguistic SupportBenchmark-agnostic — runs whatever regional-language task suite is plugged in
[SEE_IT_RUN]

See one runner execute your benchmark end to end.