Search that understands more than keywords.
Retrieval That Understands More Than KeywordsHybrid retrieval that combines semantic search with keyword matching, reranked for relevance and scoped to each document's language — so agents answer from your real knowledge base, not guesswork.
What Indic RAG delivers today
Grounded, not guessed
Retrieval Built for Real Answers
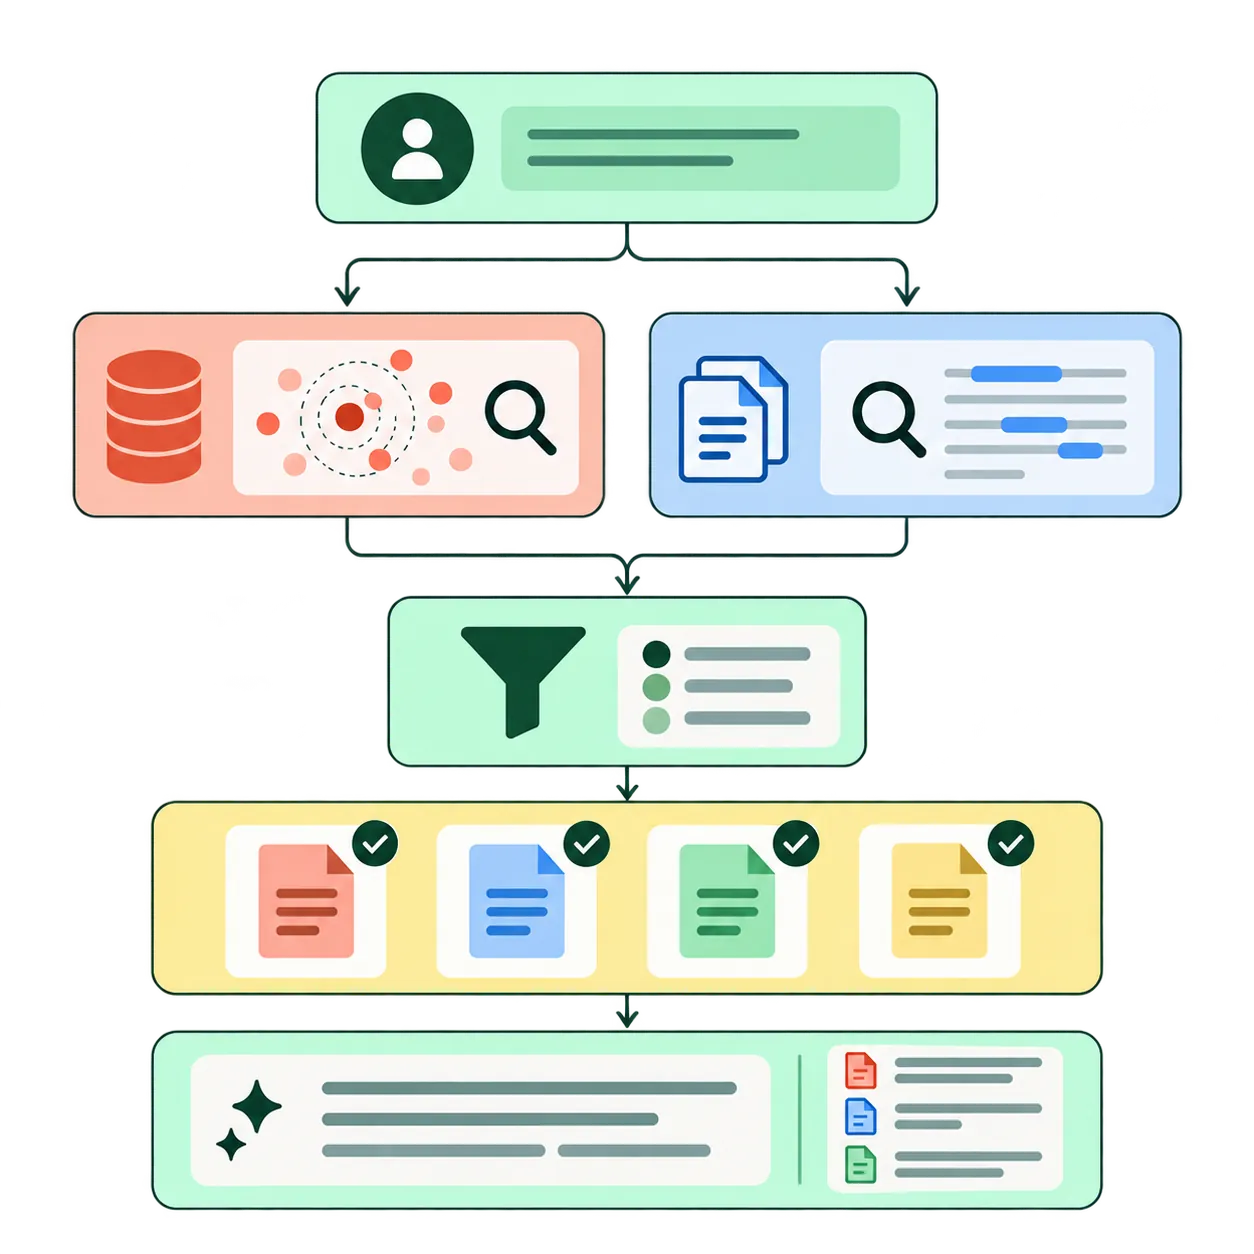
Hybrid Vector + Keyword Search
Combines semantic vector similarity with keyword and full-text matching for more relevant results than vector search alone.
Language-Aware Retrieval
Search configuration adapts to each document's language rather than assuming everything is in English, with a safe fallback when a dedicated configuration isn't available.
Pluggable Reranking
A reranking layer reorders retrieved results by relevance, designed so the underlying reranking engine can evolve without changing how the rest of the pipeline uses it.
Where Indic RAG drives value
Enterprise Knowledge Search
Teams search across internal documents and knowledge bases and get grounded answers with real citations.
- ✓Hybrid retrieval reduces missed matches compared to vector search alone.
- ✓Results are ranked for relevance before being handed to the agent.
- ✓Works across a knowledge base ingested through the platform's own pipeline.
Grounded Agent Answers
Agents pull retrieved chunks into context before answering, so responses stay grounded in real documents rather than the model's own memory.
- ✓Retrieval is scoped to the requesting tenant.
- ✓Citations trace every answer back to its source document.
- ✓Distinguishes between document content and codebase content when both are relevant.